Your AI should learn from corrected work
Fixing the same mistake weekly means the company pays twice and the workflow never compounds.
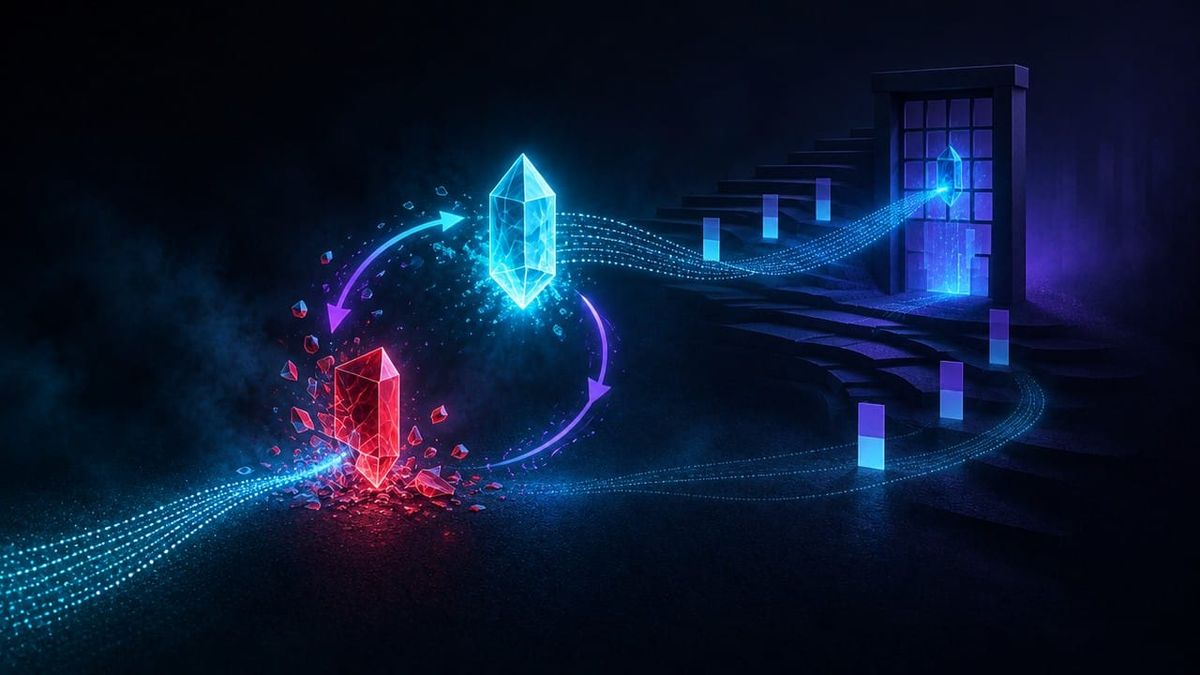
Fixing the same mistake weekly means the company pays twice and the workflow never compounds.
The correction that never becomes memory
A teammate fixes the draft. They adjust the tone, correct the customer status, remove a promise the agent should not make, and send or approve the better version.
Next week the same class of mistake returns. Different ticket, same miss. Another competent person pays again with time and attention. The workflow did not get wiser. The company just got another quiet tax.
That pattern is easy to miss because each correction looks small. Over a quarter it is a serious operating leak: judgment is spent once in the moment and never deposited into company memory.
Reframe: a correction is unfinished until it can prevent the next miss
Fixing today’s output is customer care. Capturing the approved correction as precedent is how the business compounds.
Without that second step, AI work stays in permanent tutoring mode. People lead by repeatedly repairing the same gaps instead of raising the baseline the agents execute against.
So the standard should not be, “Did someone catch it?” The standard should be, “Did the approved correction update the rule, example, or memory the workflow will use next time?”
If the answer is no, you are running a rework service, not a learning system.
What breaks when corrections do not feed the workflow
Quality depends on who is on shift. Some people catch the miss. Others do not. Customers experience lottery-quality operations.
Experts become unpaid integrators. High performers spend their edge on repetitive repair instead of harder judgment.
Trust erodes in both directions. Staff stop believing the AI will improve. Leaders over-invest in more tools because the current ones “need constant babysitting”.
Precedent never forms. The company cannot show why a decision changed, so future agents and future staff re-litigate settled calls.
The deeper issue is treating human review as a sink instead of a source. Review should improve the system, not only rescue the item.
Practical standards for learning from corrected work
1. Make corrections easy to mark as precedent
When someone edits an AI output, give them a short way to say: one-off fix, or update the workflow. If capturing learning takes a project, it will not happen on a busy Tuesday.
2. Store the why, not only the rewrite
Save what was wrong, what “good” looks like, and which rule or customer context mattered. A pasted final draft without rationale teaches less than a clear precedent.
3. Route learning to the right layer
Some corrections update a template. Some update an approval rule. Some update retrieval memory. Some need a human policy change. Put the learning where the next run will actually see it.
4. Require an owner for recurring misses
If the same correction appears repeatedly, name who must change the workflow. Recurring rework without an owner is accepted waste.
5. Review learning like you review incidents
Periodically check which corrections became precedent and which evaporated into chat. Learning rate is an operating metric even when you refuse vanity AI scores.
Watch for false learning too. A one-off customer favour should not silently become standing policy. Separate temporary exceptions from approved precedent, or the workflow will learn noise and staff will stop contributing corrections.
Five questions before you scale a reviewed AI workflow
- Where do approved corrections go after someone fixes an output?
- Who can promote a correction into standing guidance?
- How does the next run retrieve that guidance?
- What recurring misses still have no owner?
- How do we stop one-off exceptions becoming silent permanent rules?
If those answers are fuzzy, keep humans close and slow the scale-up. Speed without learning multiplies rework.
I treat this as operating design. Memory should hold decisions and corrections, not only raw chat. That is how people lead while agents improve at execution.
Paying twice is a design smell
If the same correction appears every week, the business is funding a loop that never closes. That is not a staff diligence problem. It is a missing deposit into operating memory.
A practical weekly ritual helps: pick the top recurring AI fixes, promote at least one into precedent, and confirm the next run can see it. Small deposits beat annual “knowledge base” projects that never touch the live path.
At Walter, I am focused on helping businesses run AI work with clearer ownership, shared context and visible hand-offs. Learning from corrected work is how those hand-offs get cheaper over time.
A useful assistant can draft. A trustworthy operating layer captures the human improvement: approved correction, rationale, owner and next-run visibility. That is how judgment compounds instead of leaking every week.
Speed still matters. Make the learning step lighter than repeating the fix. Teams move faster when yesterday’s correction quietly prevents tomorrow’s miss.
If your team corrects the same AI mistake every week, change the learning loop before you add more automation.
Make precedent capture easy. Store the why. Route learning to the layer the next run uses. Own recurring misses. Review what actually stuck.
Do that, and AI review becomes an investment in company memory rather than a permanent unpaid cleanup shift. The goal is simple: correct once, reuse the judgment, and stop paying twice for the same miss.
Join the waitlist at https://hirewalter.ai/