The first version of an AI workflow should be designed to fail visibly
The safest first AI workflow makes missing context, authority limits and incomplete actions visible before they become silent business errors.
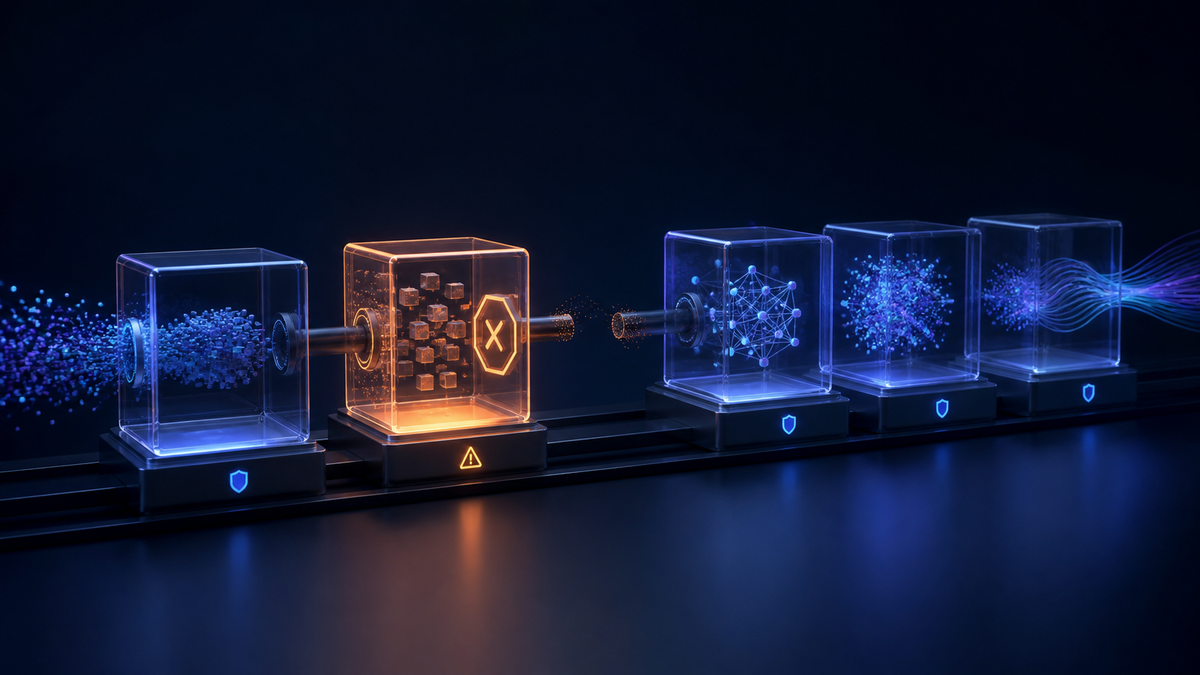
Early AI systems will encounter missing context, uncertain outputs and unexpected cases. The safest first version makes those failures obvious, contained and useful for improvement.
The first version of an AI workflow will be wrong about something. A source will be incomplete. A customer request will fall outside the expected pattern. A policy will change. An integration will time out or an action will need authority the agent does not have.
The risk is not that these failures exist. The risk is that they look like success.
A polished response can hide weak evidence. A completed automation run can conceal the fact that a record was not updated. A friendly customer message can commit the business to something nobody approved.
The safest early workflow is not the one that appears flawless. It is the one that makes uncertainty, interruption and incomplete work visible.
Silent failure is more expensive than visible failure
Teams often design pilots around the happy path. The input is clean, the examples are familiar and the person testing the system knows what the output should look like. Under those conditions, the workflow can seem ready very quickly.
Production is different. Real work includes outdated documents, conflicting instructions, unusual requests, missing fields and people who do not know the assumptions built into the pilot.
When the workflow is optimised to look smooth, it may continue through those conditions with unwarranted confidence. The mistake is discovered later, after a customer has acted on it, a manager has approved the wrong version or another system has treated the output as fact.
Visible failure brings the problem forward, when it is cheaper to understand and contain.
Visible does not mean chaotic
Designing for visible failure does not mean flooding a shared channel with technical errors or asking people to inspect every output. It means giving each known failure condition a clear state, owner and next action.
A useful first version should distinguish at least four conditions.
- Missing evidence: the required source or field is not available.
- Conflicting truth: two authoritative records disagree.
- Authority limit: the proposed action exceeds what the agent may do.
- Execution failure: the decision was made but the downstream system did not confirm the change.
These are not interchangeable. Each needs a different response. Missing evidence may require a request for information. Conflicting truth needs a named owner to resolve which source applies. An authority limit needs approval. An execution failure may need a retry or manual recovery.
One generic error message hides the operational meaning of the problem.
Make the stop state useful
A visible failure should tell the next person what happened without forcing them to reconstruct the entire run. The handoff should include the intended outcome, the step that stopped, the evidence available, the rule or boundary involved and the safest available next action.
It should also be clear whether any external change occurred. Did the agent draft a response only, or send it? Did it calculate a refund, or issue one? Did it prepare an update, or save it to the system?
This state separation is essential. A prepared action is not a completed action, and an attempted action is not proof of delivery.
The failure record becomes part of the workflow's memory. When the same condition appears again, the team can see whether it is a rare edge case or a recurring design problem.
Use failures to set the next authority boundary
The early goal is not to maximise autonomy. It is to learn where autonomy is safe.
Start with a narrow authority boundary and record the exceptions. Some failures will reveal missing context that can be added to the workflow. Some will show that a routine decision can safely move within a defined limit. Others will confirm that human judgement should remain in place.
This approach produces a better expansion path than simply reviewing a larger sample of outputs. The team learns which conditions matter, what evidence improves reliability and where the cost of being wrong changes.
Autonomy can then grow through explicit decisions rather than optimism.
Test recovery, not only generation
Most AI evaluations focus on whether the system can produce the expected answer. A production test should also ask what happens when it cannot.
Remove a required field. Introduce two conflicting sources. Ask for an action above the authority limit. Disconnect the final integration. Then observe whether the workflow stops clearly, preserves the evidence, alerts the right owner and prevents a false completion state.
A workflow that recovers well is often more valuable than one that performs perfectly on a controlled demonstration.
The Walter point of view
Reliable AI work depends on governed context, clear authority and accountable handoffs. Walter is designed around that operating model: agents should recognise when they cannot safely continue, explain the operational reason and keep the work visible until the right person or system completes it.
The purpose of a boundary is not to make the agent less useful. It is to prevent uncertainty from becoming an invisible business commitment.
A visible failure is evidence that the workflow knows where its responsibility ends.
Run one failure rehearsal
Choose a workflow that is moving toward production and deliberately break one important assumption. Use a missing source, a conflicting rule or a failed downstream update.
Check whether the case has a clear state, a named owner, a bounded next action and a record that returns to the system.
If the workflow can only demonstrate the happy path, it is not yet showing that it can operate safely. Make the failure visible first. Then use what you learn to build the next version.
Register here for early beta access of Walter